 Logos identify the maker. Blade AI is an independent supplier.
Live deal · AMD Instinct MI350P
Supermicro 10-GPU servers with AMD Instinct MI350P, available now
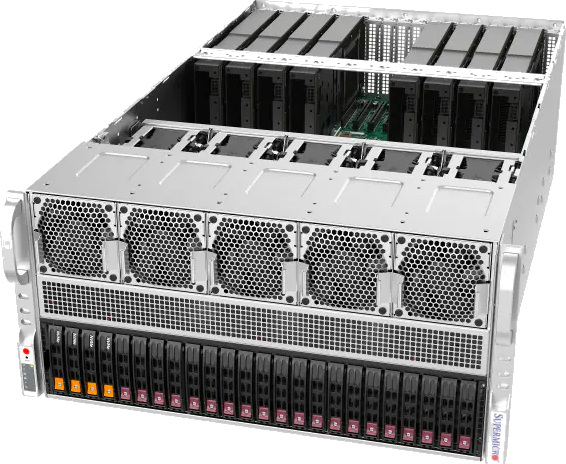
One lot of 100 Supermicro AS-5126GS-TNRT2 servers, each with ten AMD Instinct MI350P GPUs (144GB HBM3e each, 1.44TB of GPU memory per server), two AMD EPYC 9575F processors and 2TB of DDR5-6400 in a 5U chassis. For buyers who were looking at H200: more GPUs and more GPU memory per server, higher FP8 and BF16 throughput per GPU, FP4 support, and about 3 weeks to deploy against the 25 to 30 weeks new H200 orders are being quoted. PyTorch, vLLM and SGLang run on AMD ROCm today; CUDA still leads for TensorRT-LLM and custom kernels. Sold as complete servers only.
- 10AMD Instinct MI350P GPUs per server, 144GB HBM3e each
- 1.44TBGPU memory per server (an 8-GPU H200 server has 1.13TB)
- 2.3 PFLOPSFP8 per GPU (H200: 1.98)
- About 3 weeksFrom compliance to shipping (new H200 orders: 25 to 30 weeks)
The lead-time gap
How fast this one ships
-
 AMD Instinct MI350P
Supermicro 10-GPU servers, instead of new H200
Blade AI: ~3 wksThe market: new H200: 25–30 wks~25 weeks sooner than new H200
Typical lead time from end-user compliance approval. Confirmed on the quotation.
Specification
| System | Supermicro AS-5126GS-TNRT2, 5U PCIe GPU server |
|---|---|
| GPU | 10 x AMD Instinct MI350P, 144GB HBM3e, 600W, PCIe CEM |
| GPU memory, total | 1.44TB per server |
| Processors | 2 x AMD EPYC 9575F, 64 cores, 3.3GHz |
| System memory | 16 x 128GB DDR5-6400 ECC RDIMM (2TB) |
| Boot storage | 2 x 1.92TB M.2 NVMe on a hybrid M.2 RAID carrier |
| Security | TPM 2.0 |
| Management | Supermicro System Management Software node licence |
| Support | 3 years onsite next business day |
| Lead time | About 3 weeks after end-user compliance clears |
| Quantity | 100 servers (1,000 GPUs), one lot, subject to prior sale |
| Price | Confirmed on the quotation |
- One lot: 100 servers (1,000 GPUs). Once they are gone, it is back to factory lead times.
- Sold as complete servers only, not as individual GPUs.
- Offered subject to prior sale and end-user compliance. Specification, quantity and price are confirmed on the quotation.
How it compares
- FP8: 2.3 PFLOPS per GPU against 1.98 on H200. BF16: 1.15 against 0.99. FP4: 4.6 PFLOPS; H200 has no FP4.
- Where H200 still leads: memory bandwidth (4.8TB/s against 4.0), FP64 (67 TFLOPS against 36) and NVLink between GPUs.
- Software: PyTorch, vLLM and SGLang run on AMD ROCm today. CUDA still leads for TensorRT-LLM and custom kernels.
Posted 12 November 2026. Specification as supplied. E&OE.
Other live deals
- MiTAC 8-GPU servers with AMD Instinct MI350X, available nowG8825Z5: 8 x AMD Instinct MI350X 288GB, 2 x EPYC 9575F, 3TB DDR5, 8 x 400G, 8U
- Supermicro 8-GPU servers with AMD Instinct MI300X, about 6 to 8 weeksAS-8125GS-TNMR2: 8 x AMD Instinct MI300X 192GB, 2 x EPYC 9654, 2.3TB DDR5, 4 x 400GbE, 8U
- NVIDIA A100 GPU racks, complete systems, available nowZT Systems Gen 7.0 48U racks: 32 x A100 40GB SXM4 per rack, from a single rack
Register interest in this deal
Supermicro 10-GPU servers with AMD Instinct MI350P, available now: Supermicro AS-5126GS-TNRT2. We reply within one working day with the quantity still open, the price and the lead time.
GPU systems are export-controlled. Before we quote we ask who the end user is and where the hardware will be installed. We do not supply the destinations listed on our export compliance page.
How a live deal works
- Register interest with the quantity, the site and the date you need it.
- We reply within one working day with the specification, the quantity still open and the price.
- Mutual NDA, then end-user and site documents for export screening. We may decline a deal.
- Your purchase order and deposit go to the seller of record. Serial numbers and photos reach you before the balance is due.