Looking for H200? Read this first. We have 100 AMD MI350P GPU servers in stock today. 🥊
In Rocky III, the champ got comfortable and a hungry challenger took the title. Our next fight looks a lot like that.
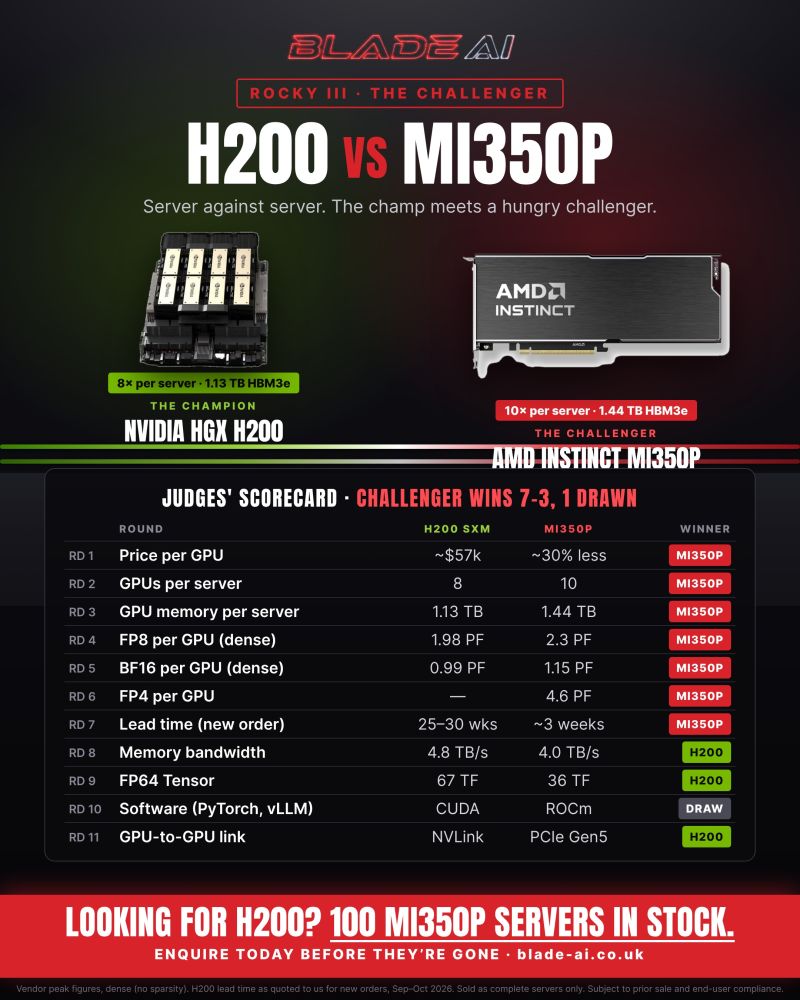
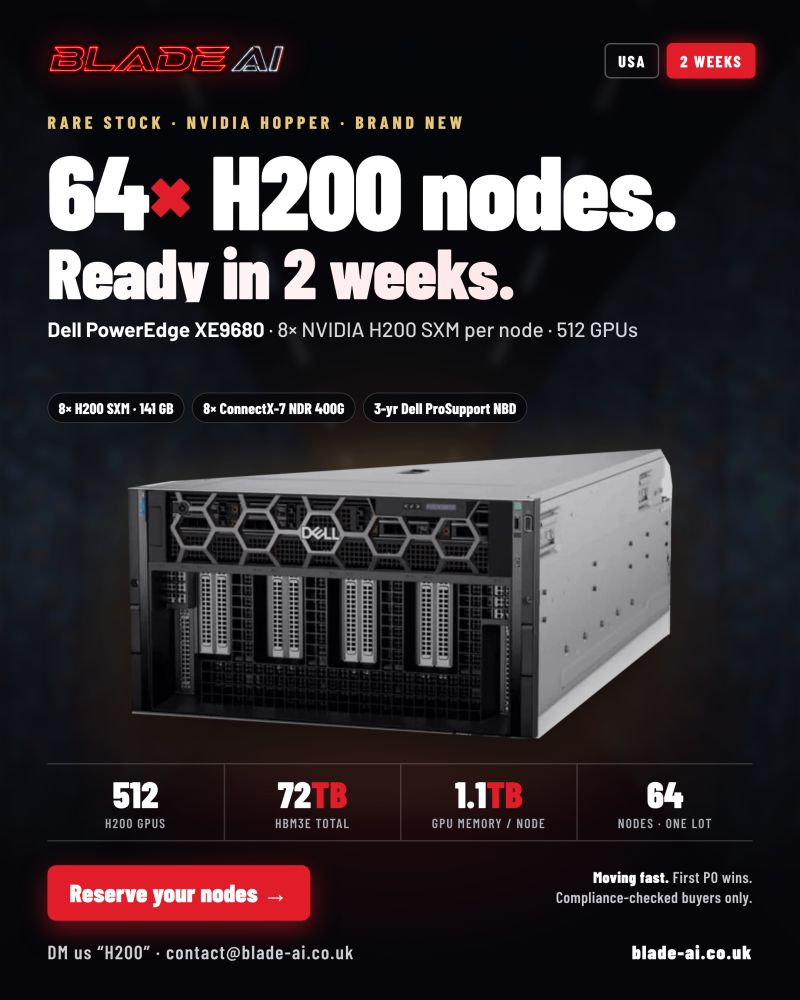
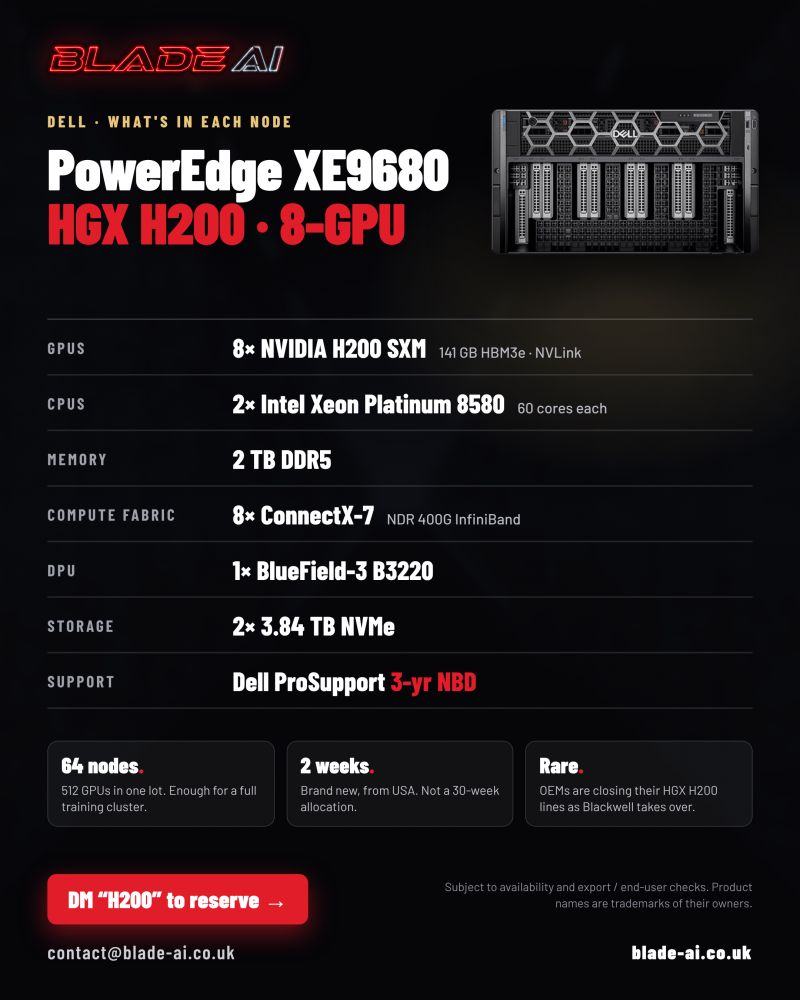
In the green corner: an NVIDIA HGX H200 8-GPU server. In the red corner: a Supermicro server with 10× AMD Instinct MI350P.
Judges' scorecard:
Round 1, price per GPU: MI350P. About 30% less than an 8-GPU H200 SXM server.
Round 2, GPUs per server: MI350P. 10 against 8, in a 5U chassis.
Round 3, GPU memory per server: MI350P. 1.44TB against 1.13TB, about 25% more in one box.
Round 4, FP8: MI350P. 2.3 PFLOPS per GPU against 1.98.
Round 5, BF16: MI350P. 1.15 PFLOPS against 0.99.
Round 6, FP4: MI350P. 4.6 PFLOPS. The H200 has no FP4.
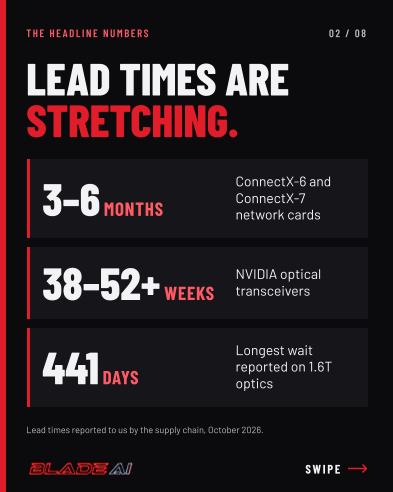
Round 7, lead time: MI350P. About 3 weeks after compliance. New H200 orders are being quoted at 25 to 30 weeks.
Round 8, memory bandwidth: H200. 4.8TB/s against 4.0.
Round 9, FP64: H200. 67 TFLOPS against 36.
Round 10, software: draw. PyTorch, vLLM and SGLang run on AMD's ROCm today. CUDA still leads for TensorRT-LLM and custom kernels.
Round 11, GPU-to-GPU link: H200. NVLink is still the champ's best punch.
Seven rounds to three, one drawn. If your stack runs on PyTorch, vLLM or SGLang, the challenger wins on price, memory per rack and time to deploy.
🚨 One lot: 100 servers (1,000 GPUs) in stock. Once they're gone, it's back to factory lead times.
If H200 was on your list, enquire today. Message us or email contact@blade-ai.co.uk with the quantity you need.
Sold as complete servers only. Subject to prior sale and end-user compliance.
#Rocky #AMD #MI350P #NVIDIA #H200 #AIInfrastructure
Blade AI
in